DonSeTch
The web, for AI agents.



Why · Demo · Sponsors · Install · Quickstart · The 4 tools · Fetch · Search · PDF · Stealth · Compare · Limits · CLI
DonSeTch gives any AI agent full web research from a single local process: fetch, search, crawl, screenshot. Four tools, zero API keys, zero accounts, Rust, one binary. The transport is built from scratch (no hyper, no Playwright, no Selenium), so the fetch tier is fast and stealthy, and the tool surface stays small enough to fit an agent's context.
Works with every MCP client (Claude Code, Cursor, OpenCode, Pi, Hermes) and as a standalone CLI.
🤝 Use Bright Data? Support DonSeTch. Their proxy, SERP and Web Unlocker products come through this partner link and part of it comes back to keep DonSeTch free. You pay nothing extra: https://get.brightdata.com/ivqwoicrrlbr Bright Data plugs into the tool itself: the
bdSERP provider, the Web Unlocker tier-3 bypass and theunlockerkey type.
✨ Why it's different
| What it does | |
|---|---|
| 🛡️ Real Chrome TLS | Drives Chrome's own BoringSSL natively. Your ClientHello IS Chrome's ClientHello, ML-DSA signature algorithms included. Emergent from the real engine, not a faked table that rots. |
| ⏱️ Temporal stealth | TLS session resumption, conditional revalidation (304), persistent cookies, connection pooling, TCP Fast Open. The loudest remaining bot tell, and nobody else fakes it. |
| 👻 Solve-and-bounce | The browser solves the challenge and hands cookies back to tier 1, which then fetches at full speed. The browser almost never fetches content. |
| 🧠 Self-improving fetch | Learns from every fetch: cookie lifetimes adapt, walls that beat a real browser twice go into cooldown, searches pre-solve known walls. Receipts in status and doctor --improve. |
| 🔑 Keyless search | 10+ backends in parallel, fused by cross-engine consensus plus local semantic reranking. No keys, $0 forever. BYOK optional. |
| 📄 Pixel-fusion PDF | Glyphs and rendered pixels come from the same content stream and are fused deterministically, with a per-region trust audit. Scanned PDFs auto-OCR. |
| 🧬 Built from scratch | Own HTTP/2 (HPACK, flow control, priority), own extraction engine, own PDF parser, own search aggregator, own crawl engine. |
| 🔗 Token control | Links render as [text](L12), results as S1…Sn, and fetch S3 just works: 3 tokens instead of 80. focus, toc, section, must_contain and since_last each cut a page down to what the agent actually needs. |
| 🪶 ~2.4k tool schema | All four tools, measured from tools/list. Every token earns its place. |
🩺 doctor |
One command sweeps config, search health, egress, TLS, browser, DNS, captive portal, secret-store permissions, and fixes what is mechanically fixable. |
🎬 Demo
(30-second walkthrough: search, bot-wall bypass, crawl)
(Pi agent session: live research with DonSeTch as a native extension)
💛 Our Sponsors
Fluxion AI provides reliable, cost-efficient access to GPT, Claude, and other leading AI models through one unified API. Save up to 70% compared with official API pricing, and get $3 in API credits when you sign up through this link.
🤝 Sponsor this project
DonSeTch is free and open source, and stays that way. Sponsorship pays for the time it takes to keep shipping.
| Tier | Price | What you get |
|---|---|---|
| 🥉 Bronze | $10/mo | Name + link in Our Sponsors |
| 🥈 Silver | $25/mo | Small logo + link in Our Sponsors |
| 🥇 Gold | $49/mo | Large logo + link, pinned at the top of Our Sponsors |
Prepaid monthly, cancel anytime. One-time sponsorships are welcome at any amount.
Pricing goes up as the project grows. It is early now, so a Gold at $49/mo is near-zero investment for any company whose product touches agent web research. If your product is part of this space (proxy platforms, search infrastructure, BYO providers, anything a DonSeTch user would plug in), Gold goes one step further: fit natively inside DonSeTch and you get the placement plus an official integration shipped in the binary itself.
Email bhandaribishesh879@gmail.com to become a sponsor.
📦 Install
npm, any platform (recommended):
npm install -g donsetch
Downloads the prebuilt binary for your platform from GitHub Releases with SHA256 verification. No build tools needed.
Homebrew (macOS/Linux):
brew tap dondai44423/donsetch && brew install donsetch
Pi agent (native extension):
pi install npm:donsetch
Registers the tools as native pi tools, spawns the binary at session start, self-updates with pi update --extensions.
DeepSeek Harness (dsh, first-class plugin):
dsh plugin --profile web add github:dondai44423/donsetch-dsh
One line and every dsh agent gets fetch, search and crawl as native donsetch_* tools, no mcp__ names and no manual MCP config: the plugin downloads the verified binary for your platform, registers the tools in-process, auto-updates with DonSeTch releases, and picks up donsetch keys add changes live. See the donsetch-dsh repo for the config reference.
Homebrew and dsh auto-track published releases.
Verify the install:
donsetch doctor          # fast local sweep, ~1 second
donsetch doctor --deep   # adds live browser + egress probes
donsetch doctor --fix    # repairs mechanical problems automatically
donsetch doctor --json   # machine-readable, also prints MCP registration blocks for your client
Install notes and troubleshooting
- Linux prebuilts: glibc >= 2.35 (Ubuntu 22.04 LTS and newer). The bundled ONNX lib keeps its own 2.27 floor, so OCR and rerank work on all of those.
- pnpm or bun: approve the build script (
pnpm approve-builds, or the bun equivalent), then reinstall. If scripts were blocked,npx donsetchinvokes the self-healing shim. --ignore-scripts: postinstall is intentionally skipped. Runnode node_modules/donsetch/install.js, ornpx donsetchto download the binary when network is available.- Proxy: set
HTTPS_PROXY(orhttps_proxy,HTTP_PROXY,http_proxy) to an HTTP CONNECT proxy. - Release mirror: set
DONSETCH_RELEASES_BASEto a mirror holding<tag>/<asset>paths. - Windows: the installer needs
tar, included since Windows 10 1803. - Windows ARM64: the x64 build runs under emulation, no native asset needed.
- musl/Alpine: published Linux binaries are glibc. Build from source on musl.
- First OCR/search run downloads models (~24MB reranker, ~37MB OCR), cached forever. Pre-seed offline boxes by copying the
ocr/rerankcache dirs.
Build from source
| Dependency | Why | Linux | macOS | Windows |
|---|---|---|---|---|
| Rust | toolchain | rustup |
rustup |
rustup |
| Go | BoringSSL build | apt install golang-go |
brew install go |
winget install GoLang.Go |
| NASM | BoringSSL asm | apt install nasm |
brew install nasm |
choco install nasm |
| CMake | BoringSSL build | apt install cmake |
brew install cmake |
winget install cmake |
| Clang | bindgen | apt install clang libclang-dev |
bundled | choco install llvm |
| LLD | PDFium link (aarch64) | apt install lld |
not needed | not needed |
git clone https://github.com/dondai44423/donsetch.git
cd donsetch
cargo build --release --features ocr,rerank,http
First build compiles BoringSSL (~2 min), cached after. Chromium is optional (tier-2 escalation only): DonSeTch auto-discovers system Chromium, Playwright's cached builds, or Edge on Windows.
On Ubuntu 22.04 and anything with bfd 2.38, link with lld: bfd cannot parse the .crel relocations rustc 1.86+ emits for aarch64, and the default link dies with "unknown architecture".
sudo apt-get install -y cmake build-essential pkg-config libclang-dev clang lld nasm golang-go
RUSTFLAGS="-C link-arg=-fuse-ld=lld" cargo build --release
The same recipe covers the prebuilt baseline: every asset from v3.4.5+ is built on Ubuntu 22.04 and runs there directly.
Feature set: default is [] (fetch, search, crawl, PDF). ocr,rerank pulls in ONNX Runtime, http enables the HTTP MCP transport. npm prebuilts ship all three on linux-x64, macOS-arm64, macOS-x64 and Windows-x64; linux-arm64 is core-only, because the aarch64 ONNX runtime deadlocks in its loader. On macOS, OCR and rerank need macOS 13.4 or newer (the minimum of the Microsoft-signed ONNX dylib that ships beside the binary). Linux ARM64 carries one more honest limit: fragile PDF (a loader hang in some paths, tracked in CI).
Selectable browser backend
Chromium is the default: headful on Xvfb/off-screen when a display exists, --headless=new only when none does. CloakBrowser is used only when explicitly selected, a bare CLOAKBROWSER_BINARY_PATH never switches it.
DONSETCH_BROWSER_BACKEND=chromium donsetch doctor             # default backend
DONSETCH_BROWSER_BACKEND=headless donsetch doctor --deep      # forced headless
DONSETCH_BROWSER_BACKEND=cloakbrowser \
  CLOAKBROWSER_BINARY_PATH=/path/to/chrome donsetch doctor --deep
Aliases: original for chromium, original-headless for headless. Public CloakBrowser downloads are opt-in (DONSETCH_CLOAK_AUTO_DOWNLOAD=1) and verified: Ed25519-signed SHA256SUMS, manifest bound to the requested Chromium version, archive SHA-256 checked, unsafe paths rejected. CLOAKBROWSER_VERSION pins a version. CloakBrowser binaries are never bundled in releases or images.
🚀 Quickstart
MCP server (for any agent). Register and go:
{
  "mcpServers": {
    "donsetch": {
      "command": "donsetch",
      "args": ["mcp", "--supervised"]
    }
  }
}
--supervised is the crash-only daemon: a panic is a blip, the daemon restarts itself, the session survives. Without a global install, use "command": "npx", "args": ["donsetch", "mcp"].
HTTP transport instead of stdio: donsetch mcp --http --port 8765, clients connect to http://localhost:8765/mcp. Sessions, cancellation, /health, token auth via DONSETCH_HTTP_TOKEN and per-request timeouts are documented in donsetch mcp --help. A request that carries a browser Origin is refused unless the page is on loopback or CORS mode (DONSETCH_HTTP_CORS, which requires the token) is on, and a server bound to loopback answers only to loopback Host names on its own port, so a web page cannot drive it and a DNS-rebound name cannot read from it.
CLI (for humans and scripts). Same engine, thin adapter:
donsetch fetch https://example.com --focus "pricing"
donsetch search "rust async patterns" --intent code
donsetch crawl https://docs.python.org --mode map --topic asyncio
If your client shows only half the result (the [meta] fold)
An MCP result has two surfaces: content (the page markdown) and structuredContent (raw URLs behind the S3 handles, next_offset, resume tokens, content_ok, thin, error codes, next_action). MCP never said which one a client renders, so clients drop one: Claude Code and VS Code keep structuredContent and discard content, OpenCode v1 (tested on 1.18.3) keeps content and discards structuredContent, and OpenCode 2 (Code Mode on by default, tested on 2.0.16) keeps structuredContent and discards content, like Claude Code. The Pi extension is another shape: it hands the model content only (structuredContent never reaches the model there), so the document arrives without the URLs behind the handles.
Symptoms: tool metadata but no page text, or page text but no citable URL behind an S3 handle, no pagination, no error codes. The fix is the same for all of them: DonSeTch folds the state into a compact leading [meta] text block, keeps the markdown as a clean block behind it, and omits structuredContent. The known clients get the fold automatically, detected by clientInfo.name at the handshake: Claude Code, VS Code, OpenCode, and the Pi extension (pi-donsetch). Any other client (a wrapper or fork under a different name, claude-code-proxy say) is not detected and keeps the token-optimal split:
DONSETCH_MCP__TEXT_ONLY=1 donsetch mcp # force the fold for every client
or in donsetch.toml:
[mcp]
text_only = true
Fail-closed like the other flags: only an explicit 1/true turns it on; the legacy DONSETCH_MCP_TEXT_ONLY name still works (donsetch config show --legacy maps the old names).
OpenCode 2.x needs one of those today. It reports clientInfo.name as cli (its process.env.OPENCODE_CLIENT ?? "cli" default, which serve never overrides), too generic to claim in the name list, and its Code Mode shows the model structuredContent only. Until OpenCode restores a usable name upstream, set text_only for it.
🎯 The 4 tools
| Tool | What it does |
|---|---|
🌐 web_fetch |
Any URL as clean markdown. HTTP first, escalates to a headless browser on bot walls. PDFs with OCR and per-page confidence, focus / toc / section, pagination, actions for in-page control, must_contain probes, archive resurrection. |
🔎 web_search |
Keyless multi-engine search: 10+ backends, consensus plus semantic reranking, query-aware official-source placement. Ranked URLs and snippets, never a scraped article dump. |
🕷️ web_crawl |
Best-first same-domain crawl. Sitemap plus frontier, focus ranking, elastic pacing, resume tokens, honest stop reasons. |
📸 web_screenshot |
Rendered PNG of any URL through the same tier-2 browser. URL goes through the usual safety guards. CLI twin: donsetch screenshot URL [--out PATH]. |
Tool schemas: donsetch tools (same JSON as MCP tools/list). Every failure is structured: a stable code (wall.challenge, guard.ssrf, deadline.hit, archive.stale, network.dns…), an errorKind (permanent, transient, walled), and a next_action line, so agents branch on codes instead of parsing prose. The model surface carries evidence and the state that changes the next action; transport telemetry (tier, quality, escalation trace, timings, engines) stays under _meta, for example _meta["com.donsetch/fetch-debug"].
🌐 Fetch
Plain HTTP first, ~100-300ms. Wall or JS shell detected, auto-escalate to the ghost browser, solve, bounce the cookies back, refetch at full speed.
DonSift extraction: HTML bytes in, agent-native markdown out. Typed blocks (heading, paragraph, list, table, code, quote, media) with heading breadcrumbs.
focus: BM25-relevant blocks only, which cuts context by 80%+ on long pages. 12-language BM25: CJK unigrams and bigrams, stopword lists, stemming, accent folding.toc+section: see the outline first, then target one section. Two cheap calls instead of one expensive one.- Token policy: links stripped by default (~30% off), link farms and wiki junk dropped, duplicates suppressed.
- Classification:
Article/Listing/Forum/Docs/Table/Page, a 0-1 quality score, and inline trust signals (focus-miss, JS-shell warning, empty content). - Page memory: every fetch is fingerprinted, so a re-fetch reports
changedwith section-level diffs, andsince_last=truecollapses a re-check to one line (~30 tokens). must_contain: verifies a claim against the full page but returns MATCH/NO-MATCH plus up to 3 excerpts (~60 tokens instead of 4k).archive=auto: a dead link serves the nearest Wayback snapshot, honestly labeled with its age.stitch=true: walksrel=nextinto one call with part markers.deadline_mseverywhere: real MCP cancellation, progress notifications, ms cost footer. Nothing can silently hang.- Domain adapters: Reddit, npm/PyPI/crates.io/Go/RubyGems, GitHub, Stack Overflow, Wikipedia and docs sites get restructured from each site's own keyless surfaces. Labeled
via=adapter:…, kill-switchable. - Anti-cloak check: on decoy-prone domains, tier-1 responses are equivalence-checked against a headless render, so
decoy suspectedis stamped instead of silently passing as content.
Tier 3 bypass (opt-in). When the ghost itself hits a hard wall, fetch falls back to Bright Data Web Unlocker if a key is configured (donsetch keys add unlocker <key>[::zone]). The unlocker solves server-side, captchas included, and returns rendered HTML into the normal pipeline. Failures carry exact guidance (token rejected, zone not found, balance empty, rate limit, target still walled) on the escalation trace, and donsetch doctor --deep validates token and zone for free before the first paid call. Every successful unlock is cached locally (URL-hash keyed, sliding 6h TTL, 200 entries, parallel fetches share one paid call), so the same page inside the TTL costs nothing. All of it lives in the [bypass] config section: donsetch config show. DonSeTch works identically without it.
Anti-bot results (headless tier)
| Site | Protection | Status |
|---|---|---|
| Cloudflare-protected sites | interstitial | ✅ 200 OK |
| DataDome sites | DataDome | ✅ 200 OK |
| Stack Overflow / Medium | Cloudflare | ✅ 200 OK |
| bot detection | ✅ 200 OK | |
| Interactive captchas | hCaptcha / reCAPTCHA / Turnstile | ⛔ honest block without a key (with an unlocker key: ✅) |
🕷️ Crawl
Same-domain, best-first. Two phases: sitemap discovery (cheap URL inventory), then a Governor-paced frontier walk with extraction per page.
- Modes:
full(map + content),map(URL inventory only),content(BFS from the seed, no sitemap). - Focus-ranked frontier:
focus="query"ranks pages by BM25 relevance over link text and URL path, and crawls only matches. No semantic matching before fetch: a link sharing no token with the query is never enqueued. - Adaptive pacing: the Governor paces per (host, lane). 429/503 back off on host signals, host-declared waits (
Retry-After, robotsCrawl-delay) are honored in full, and everything self-inferred caps at ~7s. Zero artificial dwell on the fetch path: stealth through truth, never time. - Crawl-shape: frontier pops get a seeded reader-like jitter so repeated crawls never replay one identical, score-eager order into server logs. Ordering only, payloads untouched. Kill switch:
DONSETCH_NO_CRAWL_SHAPE=1. - Resume tokens: a stopped crawl resumes in one call, valid 30 minutes, survives restarts.
- Near-duplicate detection: title plus first 200 chars, hashed.
- Honest stop reasons:
FrontierEmpty,MaxPages,CharBudget,DepthLimit,Deadline,ThrottledOut. - Cross-process politeness: one host-pace store shared by every crawler on the box, so two runs against one site do not double the rate.
🔎 Keyless search
No API key, no account. Six keyless engines across four independent index families, plus eight official verticals, run in parallel on your machine, then merge, dedupe and rank.
- Backends: Bing family (Bing, DuckDuckGo, Yahoo), Brave, Mojeek, Google, plus keyless verticals (GitHub, Wikipedia, HN, Semantic Scholar, arXiv, StackExchange, MDN, Google News).
- Native Google, browser-free: HTTP through the legacy mobile endpoint on the existing Rust transport, with seven experimentally verified Nokia profiles (
6230-03.15by default). A profile that succeeds stays preferred per egress, CAPTCHA advances the cursor circularly, rate limits do not. Retry, pacing and quarantine use the same policy as every other engine. Availability depends on Google and your network; see configuration and limits. - Ghost SERP cascade: if the fan-out and its retry wave leave the merge thin (under 3 lanes or under 15 hits) and native Google failed, one headless render can recover Google's desktop SERP. It costs nothing when healthy, only fires under underdelivery, and reports itself honestly as
google_ghost. - Semantic reranking: a local ONNX cross-encoder (
ms-marco-MiniLM-L-6-v2, 23MB) reads query + title + snippet through full attention, blended 60/40 with RRF + BM25 + consensus. A post-enrichment top-up re-scores close calls using the destination page's real title and description instead of SERP fragments. - Consensus: a URL several independent indexes return gets a boost. Every result carries
score,consensus(independent index families) andengines, and the compact surface shows· N sources. - Learned engine health: per-engine trust EWMAs and chronic-failure quarantine survive restarts, so dead engines get benched instead of burning fan-out slots on every query.
- Entity coverage: anchor entities (B-tree, version numbers, years) are checked against results. Wrong entity, 0.3x.
- Honest reporting:
weak=truemeans low consensus, per-engine status is always visible, and there is no fake "no results". - Warm handoff: search pre-fetches the top results, so the next
fetch S1serves from cache in ~3ms. It also pre-solves: if the top result's domain is a known wall, a bounded background solve starts while the agent reads. - Query compiler:
site:,filetype:andintitle:are sent only to engines that honor them, and SERP instant answers are extracted with their source URLs.
Keyless quality, 110 questions across 11 niches with no keys: 95.5% answer-in-snippet against Tavily's published 93.3% (LLM-graded). Reproduce with python3 bench/search_quality.py --verbose; methodology and per-niche numbers live in the script. Search-quality caching for the bench lives in ~/.cache/donsetch/bench-search/, delete it when comparing binaries.
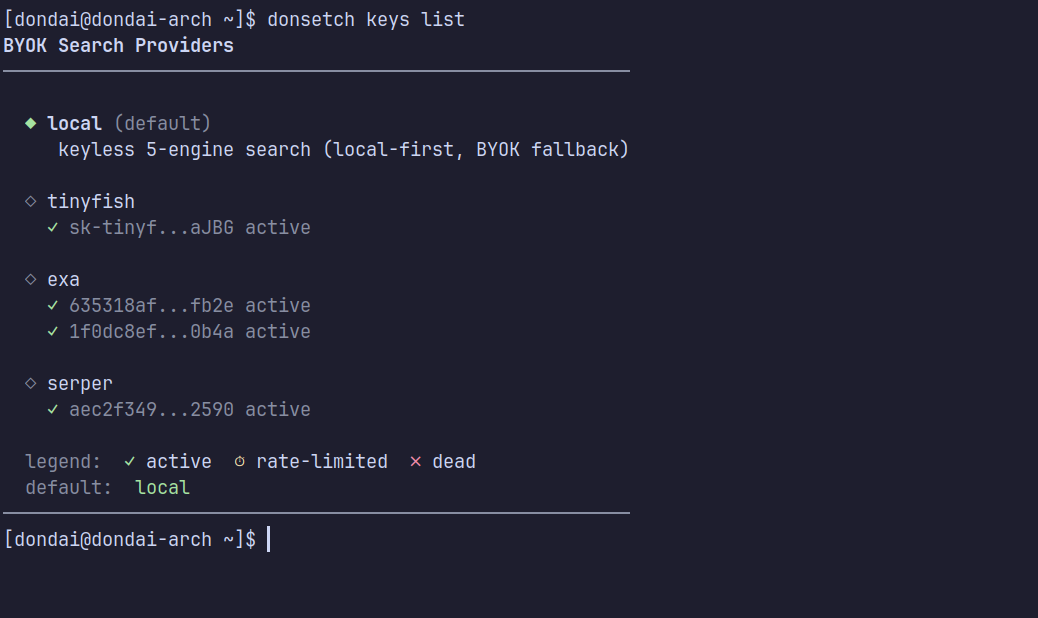
BYOK, optional and never required
Paid providers add rate limits and premium sources on top of the keyless chain.
donsetch keys add tavily tvly-...       # Tavily
donsetch keys add exa sk-exa-...        # Exa (stackable)
donsetch keys add serper ...            # Serper.dev
donsetch keys add serpapi ...           # SerpApi
donsetch keys add serpbase sb-...       # SerpBase Google SERP (100 free searches)
donsetch keys add bravesearch ...       # Brave Search API
donsetch keys add tinyfish sk-...       # TinyFish (free tier)
donsetch keys add parallel nKil3...     # Parallel AI (fast mode)
donsetch keys add bd 576d013c...        # Bright Data SERP
donsetch keys add unlocker <key>[::zone]  # Bright Data Web Unlocker
donsetch keys default local             # dispatch order: keyless first
- Stack keys per provider: two Exa keys are one 3,000-credit pool.
donsetch keys export/importmoves the store. - Automatic fallback to keyless when a provider errors or runs dry, per-key rate-limit cooldown and depletion tracking.
- The native adapter list is deliberately short, only the biggest services get one. Everything else belongs in the plugin system below, wired by you, running in the same chain.
- Bright Data SERP, Web Unlocker and the proxy/data products are available at get.brightdata.com (affiliate link).
Search plugins: any provider, no release needed
Not natively supported is not the same as unsupported. Register any executable that answers a small stdin/stdout JSON contract and DonSeTch treats it like any other provider: default chain, fallback, attribution. Any language works.
donsetch keys add plugin searxng --cmd 'python3 ~/searxng-adapter.py' --test
Request on stdin, response on stdout:
{"format":1,"query":"rust async","max_results":8,"intent":"web","deadline_ms":30000}
{"format":1,"results":[{"title":"...","url":"https://...","snippet":"...","score":0.9}]}
Errors: exit non-zero with a message on stderr, or answer {"format":1,"error":"...","retryable":true,"error_kind":"rate_limited"}. error_kind is optional and says what actually went wrong: invalid_key, credit_depleted, rate_limited, server_error, network_error. Report one of the first three and the plugin is parked the way a native key in that state is parked, rate-limited for a 60s cooldown then retried, invalid or depleted until you re-register it with keys add plugin, and keys list shows which. Leave the field out and nothing changes: retryable alone still only picks between retrying this search elsewhere and reporting the failure. Constraints that keep it reliable: hard timeout (default 30s, --timeout to change), 8 MiB stdout cap, direct exec with no shell, killed on cancellation, and a malformed response degrades gracefully down the fallback chain. Keys belong in the adapter's own environment, never in DonSeTch config.
📄 PDF + OCR
PDFs are detected by Content-Type or %PDF magic and parsed through a custom PDFium FFI. No external PDF library, no Python subprocess.
Glyphs and rendered pixels come from the same content stream, so they are already aligned. Pixels tell the truth about structure, glyphs tell the truth about text, and the fusion is deterministic: no hallucination.
| Mechanism | What it does |
|---|---|
| Pixel-fusion rule extraction | Tables and borders detected on the rendered bitmap. A rule line is a fact, not a hypothesis. |
| Span detection by ink continuity | A cell spans a separator iff the separator has no ink under it. Deterministic colspan/rowspan. |
| Trust audit + arbitration | The glyph stream is authoritative unless there are zero glyphs plus pixels (a scan) or 30%+ PUA garbage. Corrupt regions get OCR'd even when neighbors read fine. |
| Orientation canonicalization | Vertical and rotated text run one pipeline, with coordinate frames rotated. |
| Confidence honesty | Verbatim glyphs, or OCR with per-line confidence and [uncertain: …] markers below threshold. |
| Forms as data | AcroForm widgets become name/type/value triples. |
Tier B, lazy: OCR through the PP-OCR cascade (En → Zh → Deva) for scans and broken ToUnicode pages.
Battle test results
40-document corpus, zero garbage output, 6-14x faster than the Python alternatives, 120/120 fuzz clean.
| Document type | Result |
|---|---|
| Academic papers | ✅ clean text, math symbols recovered |
| Scanned documents | ✅ OCR'd, confidence-scored |
| Tax forms | ✅ forms as data |
| Multi-column layouts | ✅ reading order preserved |
| Encrypted or corrupt PDFs | ⛔ honest flag with the reason |
| Nepali UDHR (broken ToUnicode) | ✅ 10,542 chars at 86% confidence (pymupdf: 28) |
🖱️ Browser actions: page control inside one fetch
web_fetch takes an actions array, executed in the real browser before extraction:
{
  "url": "https://duckduckgo.com",
  "actions": [
    { "do": "type", "selector": "input[name=q]", "text": "rust async tokio" },
    { "do": "press", "key": "Enter" },
    { "do": "wait_text", "text": "tokio" }
  ],
  "focus": "tokio"
}
Steps: wait, wait_selector, wait_text, click, hover, type (human cadence), press, scroll. Up to 16 steps, deterministic waits, per-step results in structuredContent.actions. Search flows, form submits, load-more buttons: one call, no separate browser tool.
🛡️ Stealth: Chrome TLS, not Chrome-like
Everyone else patches a foreign TLS stack to resemble Chrome and ships hardcoded fingerprint tables that rot. DonSeTch drives Chrome's own BoringSSL with Chrome's native behaviors on: GREASE, extension permutation, ECH-GREASE, ALPS, SCT, OCSP, cert compression. The ClientHello comes out of the same machinery Chrome uses.
Verified against live Chromium, including the browser installed on your machine
A dev rig in the repo captures the real browser's raw stream, and the parity expectations are generated from those captures, never hand-edited. New browser version: re-run the rig, diff.
| Signal | Match |
|---|---|
| JA4 | cipher hash identical to Chrome |
| Akamai h2 fingerprint | exact match |
| SETTINGS + WINDOW_UPDATE preface | byte-identical, CI-asserted |
| Request HEADERS priority | [E=1 dep=0 weight=255] plus the PRIORITY flag, exact |
| h2 header order | sec-ch-ua → sec-ch-ua-mobile → sec-ch-ua-platform, exact |
| sec-ch-ua brands | reflects the installed binary: Chromium first, greased Not=A?Brand v=99, Google Chrome brand only when the binary is branded |
| Extension set | identical, contents differ only in random key material |
Own HTTP/2 stack. Off-the-shelf h2 does not expose pseudo-header order, the exact SETTINGS set, WINDOW_UPDATE values or HPACK indexing strategy, all of which are fingerprintable. So DonSeTch has its own: full HPACK (257 Huffman symbols, 61 static entries), frame engine (SETTINGS, DATA, WINDOW_UPDATE, PING, GOAWAY, RST_STREAM, CONTINUATION, PRIORITY), request HEADERS carrying Chromium's priority flag and block, flow control with replenishment, TLS 1.3 session resumption, connection pool. The h2 preface is asserted byte-identical to Chromium in CI, so a detectability regression is a build failure.
Temporal stealth. The part that is not in the bytes:
| Mechanism | Why it matters |
|---|---|
| TLS session resumption | Scrapers never resume. Chrome always does. |
| TCP Fast Open (warm hosts, Linux) | Repeat navigations send data on the SYN, like Chrome. |
| h2 connection pooling | A fresh connection per request is a bot signal. |
| Conditional revalidation | 304 means serving from cache. Browsers do this. |
| Happy Eyeballs | IPv6/IPv4 race with a 250ms stagger. |
| Persistent cookie jar | No cookie memory is a bot. |
One identity per fetch. Per-domain personas drive Accept-Language, the ghost viewport and navigator.languages, so tier 1 and the browser claim the same person. The profile is derived from the browser actually installed, and donsetch --version tells you which one it detected.
👻 Solve-and-bounce
The browser almost never fetches content. It exists for the two things HTTP cannot do: pass a JS challenge and execute a JS-rendered page. Its output is cookies (handed to tier 1, which then fetches at full speed) or rendered HTML (handed to the extraction engine).
| Step | What happens | Speed |
|---|---|---|
| 1. Tier 1 | Fast stealth HTTP | ~100-300ms |
| 2. Wall detected | Cloudflare / DataDome / PerimeterX / Akamai | - |
| 3. Ghost solves | Headless browser clears the challenge and harvests cookies | ~2-6s |
| 4. Bounce | Cookies to tier 1, refetch at full speed, browser sleeps | ~100-300ms |
| 5. After | Tier 1 with warm cookies, browser stays asleep | ~100-300ms |
Raw CDP launch without automation flags, so navigator.webdriver is natively false. Nothing is injected before page scripts: a real window, real GPU, real locale, a real PluginArray, and the window.chrome object Chrome actually ships. Where a stealth plugin patches a property so it looks less automated, this leaves the real one alone, because a patched property is a fingerprint of its own.
Process lifecycle, the RAM-smart part
The ghost is SIGSTOP'd (frozen) after 20s idle and reaped after 10 minutes frozen.
| State | RAM | CPU | Wake time |
|---|---|---|---|
| Active | full | real | - |
| Frozen | mapped but cold | 0 | ~50ms |
| Reaped | freed | 0 | ~1-2s relaunch (the profile keeps its warmth) |
Crash-transparent: a thaw that finds a dead browser silently relaunches. The persistent profile keeps cookies and clearance state across restarts.
🧠 Self-improving fetch
Every fetch is an action and an observation. Pure deterministic state, no ML, and the loop converges: the more you use it, the less it escalates.
| Visit | Route | What happens |
|---|---|---|
| 1, unknown | Cold |
tier 1 → walled → solve → store cookies |
| 2, fresh | Warm |
tier 1 with cookies, browser asleep |
| N, expired | SkipToSolve |
straight to ghost, no doomed round-trip |
| M, 24h later | RecheckCold |
the wall may be gone, try tier 1 cold |
| Wall beat the browser twice | SolveCooldown |
honest sub-ms failure with exponential backoff (15m → 2h cap) instead of burning a 20-40s browser cycle per attempt |
Cookie lifetime converges: observed_lifetime = min(previous, now - last_solved). Only clearance cookies persist (cf_clearance, datadome, _abck); tracking cookies are filtered out.
A wall that survives two real-browser solves is remembered, so future fetches answer honestly in milliseconds until the backoff lapses. A single failure never gates a domain, and any real solve or tier-1 cold success clears the memory. The daemon learns what its own environment cannot do.
Per-intent engine trust, egress-class domain profiles (cookies never cross exits), domain quality priors and crawl governor ladders all feed the same loop, all local, with receipts in donsetch status and donsetch doctor --improve. Disable disk state with DONSEEK_NO_DISK_STATE=1.
🏗️ Built from scratch
Every layer in Rust, no dependency on existing OSS web tooling.
| Component | What | Where |
|---|---|---|
| 🛡️ DonShadow | Tier-1 stealth HTTP, BoringSSL TLS, own h1 + h2, temporal stealth, cookie jar | src/fetch/ src/transport/ |
| 👻 DonGhost | Tier-2 ghost browser, CDP without Runtime/Console/Debugger, solve-and-bounce, SIGSTOP lifecycle | src/ghost/ |
| 📝 DonSift | HTML → markdown, block model, 12-language BM25 focus, token policy | src/extract/ |
| 🔎 DonSeek | Keyless multi-engine search, RRF + BM25 + consensus + semantic reranking | src/search/ |
| 🕷️ DonTread | Crawl engine, sitemap, focus frontier, Governor pacing, resume tokens | src/crawl/ |
| 📄 DonSheet | PDF extraction, PDFium FFI, pixel-truth fusion, OCR cascade, forms | src/pdf/ |
| 🔌 MCP daemon | stdio + HTTP servers, JSON-RPC 2.0, four tools, crash-only supervisor | src/mcp/ |
1,300+ tests. Zero clippy warnings: cargo clippy --all-targets --features ocr,rerank -- -Dwarnings is the law, and CI runs the full matrix on Linux, macOS and Windows.
⚙️ Configuration
Every runtime knob lives in one typed config (src/config.rs), layered, later wins:
- Compiled defaults. A bare
donsetch mcpstays the law: zero config needed. - Legacy env vars (the pre-v4 names,
DONSETCH_NO_CRAWL_SHAPEsay). Honored exactly as before, reported as deprecated bydoctor. donsetch.tomlat<config-dir>/donsetch/donsetch.toml, or anywhere viaDONSETCH_CONFIG=/path/file.toml. Unknown keys and bad values are hard errors naming the file.DONSETCH_NO_CONFIG_FILE=1skips the file layer (setting both is an error).- New env names:
DONSETCH_<SECTION>__<KEY>, soDONSETCH_FETCH__PDF_MAX_MB=25.
Sections: transport, mcp, paths, state, proxy, tls, persona, cli, fetch, bypass, search, browser, debug.
[fetch]
h3 = true               # opt into the h3 lane
shadow_fetch = "never"  # or "auto" / "always"
pdf_max_mb = 100
dns_cache_ttl_secs = 30 # seconds a resolved name is reused in-process, 0 disables

[bypass]
max_daily = 100
Booleans take true/false, enums take their listed spellings.
donsetch config showprints every knob with its value and its origin (default, legacy, file, env).donsetch config show --markdownprints the full reference table, one row per knob.donsetch config show --legacymaps every old env name to its config key.donsetch doctorwarns about the legacy vars active in your shell, mapped to their keys.
💻 CLI
Thin adapter over the same engine the MCP server uses.
| Command | What it does |
|---|---|
donsetch fetch <url> |
Fetch as clean markdown (--focus, --max-chars, --json) |
donsetch search <query> |
Search, keyless + BYOK (--intent, --max-results) |
donsetch crawl <url> |
Crawl (--mode map|full|content, --topic, --max-pages) |
donsetch screenshot <url> |
Render to PNG (--out) |
donsetch mcp |
MCP server (stdio, or --http --port N) |
donsetch doctor |
Health check and auto-fix (--deep, --json, --fix) |
donsetch status |
Version, keys, proxies, cache, health overview |
donsetch keys |
BYOK providers and plugins (add, list, default, export) |
donsetch proxy |
Proxy management (add, list, check, remove, clear) |
donsetch login |
Authenticated sessions for walled sites (--list, --status, --logout, --import) |
donsetch config |
show, --markdown, --legacy |
donsetch tools |
Tool schemas as JSON, same as MCP tools/list |
donsetch update / rollback |
Self-update from GitHub Releases, and revert |
🔀 Proxies
Fetch dials direct by default, which keeps the stealth guarantee intact: a proxy you configured is a proxy that sees your traffic. But it follows the curl/openssl convention when the environment asks for it:
HTTPS_PROXY/HTTP_PROXY/ALL_PROXY(any case) route fetches through that proxy, andNO_PROXYexempts.DONSETCH_NO_ENV_PROXY=1disables the convention entirely.- HTTP CONNECT proxies get an interception-safe handshake (no GREASE/ALPS/ECH/compress-cert), because TLS-terminating middleboxes re-sign with their own stack and some reset on exotic ClientHellos. SOCKS5 keeps the Chrome-true handshake, TLS rides end-to-end.
SSL_CERT_FILE/SSL_CERT_DIRload into the trust store, which is the only way re-signed certificates verify in an intercepting network, exactly like curl.donsetch doctorreports the whole posture: resolved env proxy, kill-switch state, system and environment trust stores, plus a live check that names the interception fix when it fails.
Search and crawl rotate proxies across lanes, each with durable health: sticky per-host lanes, persona-exclusive exits, RTT-aware pacing, burned lanes remembered across restarts. A direct dial that fails is not a dead link, and a lane that dies does not silently take a domain with it.
donsetch proxy add <url>            # rotate-able proxy entry
DONSEEK_PROXIES="url1,url2"         # env form, comma separated
donsetch proxy list                 # list, credentials masked
donsetch proxy check                # live connectivity test
donsetch proxy remove <n> && donsetch proxy clear
🔐 Logged-in sessions
Pages behind a login (x.com, gated docs, internal tools) need a real session. donsetch login gives you one without ever seeing your credentials:
donsetch login x.com          # opens YOUR browser, you sign in, press Enter
donsetch login --list         # stored sessions (names and counts only)
donsetch login --status x.com # one domain, in detail
donsetch login --logout x.com # forget a domain
donsetch login --import cookies.txt x.com   # servers and CI, Netscape format
- Credentials never enter DonSeTch. It opens a real Chromium on your display in a dedicated profile, never the automation one. You type into the browser. No keystroke capture, no screenshots, no CDP attach until you press Enter.
- Afterwards the cookies are harvested, filtered to session-worthy ones, and stored in the same 0600 vault the fetch engine already replays, so tier-1 fetches and tier-2 renders of that domain carry your login immediately, with no daemon restart. A post-login probe verifies wall detection (redirect to /login, 401/403) and surfaces it in
--list. - The registry (
auth-state.json) stores metadata only: names, counts, expiries, probe verdicts. Never values. - Multi-site: run bare
donsetch login, sign into as many tabs as you like, press Enter once.
🐳 Docker
docker build -t donsetch-mcp .
docker compose up -d                 # loopback-only by default
Multi-stage build, non-root user, optional Chrome, resource limits in the compose file. An opt-in http profile serves the HTTP transport with a healthcheck, and docker compose stop gives in-flight tier-2 fetches a 45s grace period.
🧭 Pick the right tool
DonSeTch is a rapid-fire research tool: search, read, verify. A search, a fetch or two, a docs page, one PDF. Its speed is the point, and that speed is its stealth for one-shot reads.
It is NOT built for tasks where an agent "works through" a defended site the way a person would:
- Bulk document harvesting: discovering and downloading many PDFs from one repository in a single run.
- Long sessions against one site: page after page, at machine speed, same IP, no human pauses.
- Mass extraction: mirroring a file library, collecting a dataset, systematic downloads.
DonSeTch will probably work on those, and nothing stops it. But every request fires hundreds of times faster than a human, and a defended site reads that pattern itself as a bot, not just the fingerprint. The realistic risk is an IP-level block, sometimes on your whole network mid-run. When that happens it is the task shape, not a fetch-layer failure: the same page fetched once, as a research read, is fine.
For that other shape of work, use Bladebro: a real browser doing what a human does, page by page, download by download, at a human's pace. Slower than DonSeTch by design, because over a long session against a defended site, looking human beats being fast.
Rule of thumb: one-shot research = DonSeTch. Working a defended site like a person to collect things = Bladebro.
⚠️ Gotchas & honest limits
| Surprise | Why |
|---|---|
| First build ~2 min | BoringSSL compiles from source, cached after. Go is a build dependency too, BoringSSL's build system is Go-based. |
| OCR and rerank are not in the default build | ONNX Runtime is heavy and optional: --features ocr,rerank. Prebuilts ship them on linux-x64, macOS-arm64, macOS-x64 and Windows-x64. |
| First OCR/rerank use downloads models | ~24MB reranker, ~37MB OCR, cached forever. |
| Captchas need an unlocker key | hCaptcha, reCAPTCHA and Turnstile cannot be solved locally, by design. With donsetch keys add unlocker <key>[::zone] they come through rendered; without one you get a clear honest error, never a hang. |
| robots.txt is ON for crawl | respect_robots=true for crawl. fetch does not check robots. |
| Keyless search rate-limits without a proxy | It hits engines from your IP. Set DONSEEK_PROXIES for heavy use. |
| Rerank in a CPU-limited container | Auto-clamped to cgroup parallelism on Linux, DONSEEK_RERANK_THREADS to override. |
| It cannot | Why |
|---|---|
| Solve interactive captchas locally | hCaptcha, reCAPTCHA, Turnstile: an honest dead end, no solving service by design. |
| Send ML-DSA post-quantum signatures | BoringSSL 5.1 lacks them. Lands when BoringSSL has it. |
| Search with every engine down | An error with per-engine status. Honest, never fake. |
| Replace a human working a defended site | See "Pick the right tool" above. |
🆚 How it compares
The honest summary: nothing else in this space combines a real Chrome TLS stack, browser-free keyless search, PDF pixel-fusion and local-only operation in one binary.
| DonSeTch | Hound | Crawl4AI | Jina Reader | Firecrawl | |
|---|---|---|---|---|---|
| Language | Rust, one binary | Python | Python | Python (API) | TypeScript |
| TLS fingerprint | Chrome's own BoringSSL | curl-impersonate | requests | their servers | their servers |
| Own HTTP/2 + temporal stealth | yes | no | no | no | no |
| Browser tier | solve-and-bounce | browser fetches all | browser fetches all | n/a | n/a |
| Search | keyless, 10+ engines, local rerank | keyed | no | yes | no |
| Crawl | yes, resume tokens | yes | yes | no | cloud only |
| PDF + OCR | pixel-fusion + PP-OCR | yes | partial | yes | cloud, paid |
| Self-improving routing | yes, local state | no | no | no | no |
| Runs locally, no account | yes | yes | yes | no | self-host or paid |
| MCP server | first-class | yes | community | yes | build it |
| Tool schema | ~2.4k tokens | ~2.7k | varies | n/a | varies |
| License | AGPL v3 | MIT | Apache 2.0 | proprietary | MIT |
Against Firecrawl, head to head, same tasks, live. Firecrawl is a paid cloud API, DonSeTch is free, local and keyless:
- Fetch: Wikipedia comes back 16x smaller (16KB against 267KB). An arXiv PDF is 22x faster and 4.4x smaller (1.4s/16KB against 32.6s/71KB). Reddit: Firecrawl refuses the site, DonSeTch returns the real feed.
- Crawl: 2.5x faster on the same docs target (18.7s against 47.6s), with
--topicranking the frontier instead of firehosing, and an honest small failure when the topic has no match instead of verbose unrelated content. - Search: Firecrawl is genuinely faster (1-2s against 5-7s) and leans mainstream authority. DonSeTch leans technical specificity, matched or beat it on exact GitHub issues, and costs far fewer tokens per query.
🤝 Contributing
PRs welcome, see CONTRIBUTING.md. Before submitting: just check, just t <scope> for the area you touched, and just lint (clippy with -Dwarnings). CI runs the full matrix on three platforms. AGPL v3: all contributions land under the same license.
📄 License
Copyright (c) 2026 Bishesh Bhandari. AGPL-3.0, see LICENSE.
